Quantitative Results
Sakana Fugu
の性能:定量評価
Fugu Ultra (v2.0)
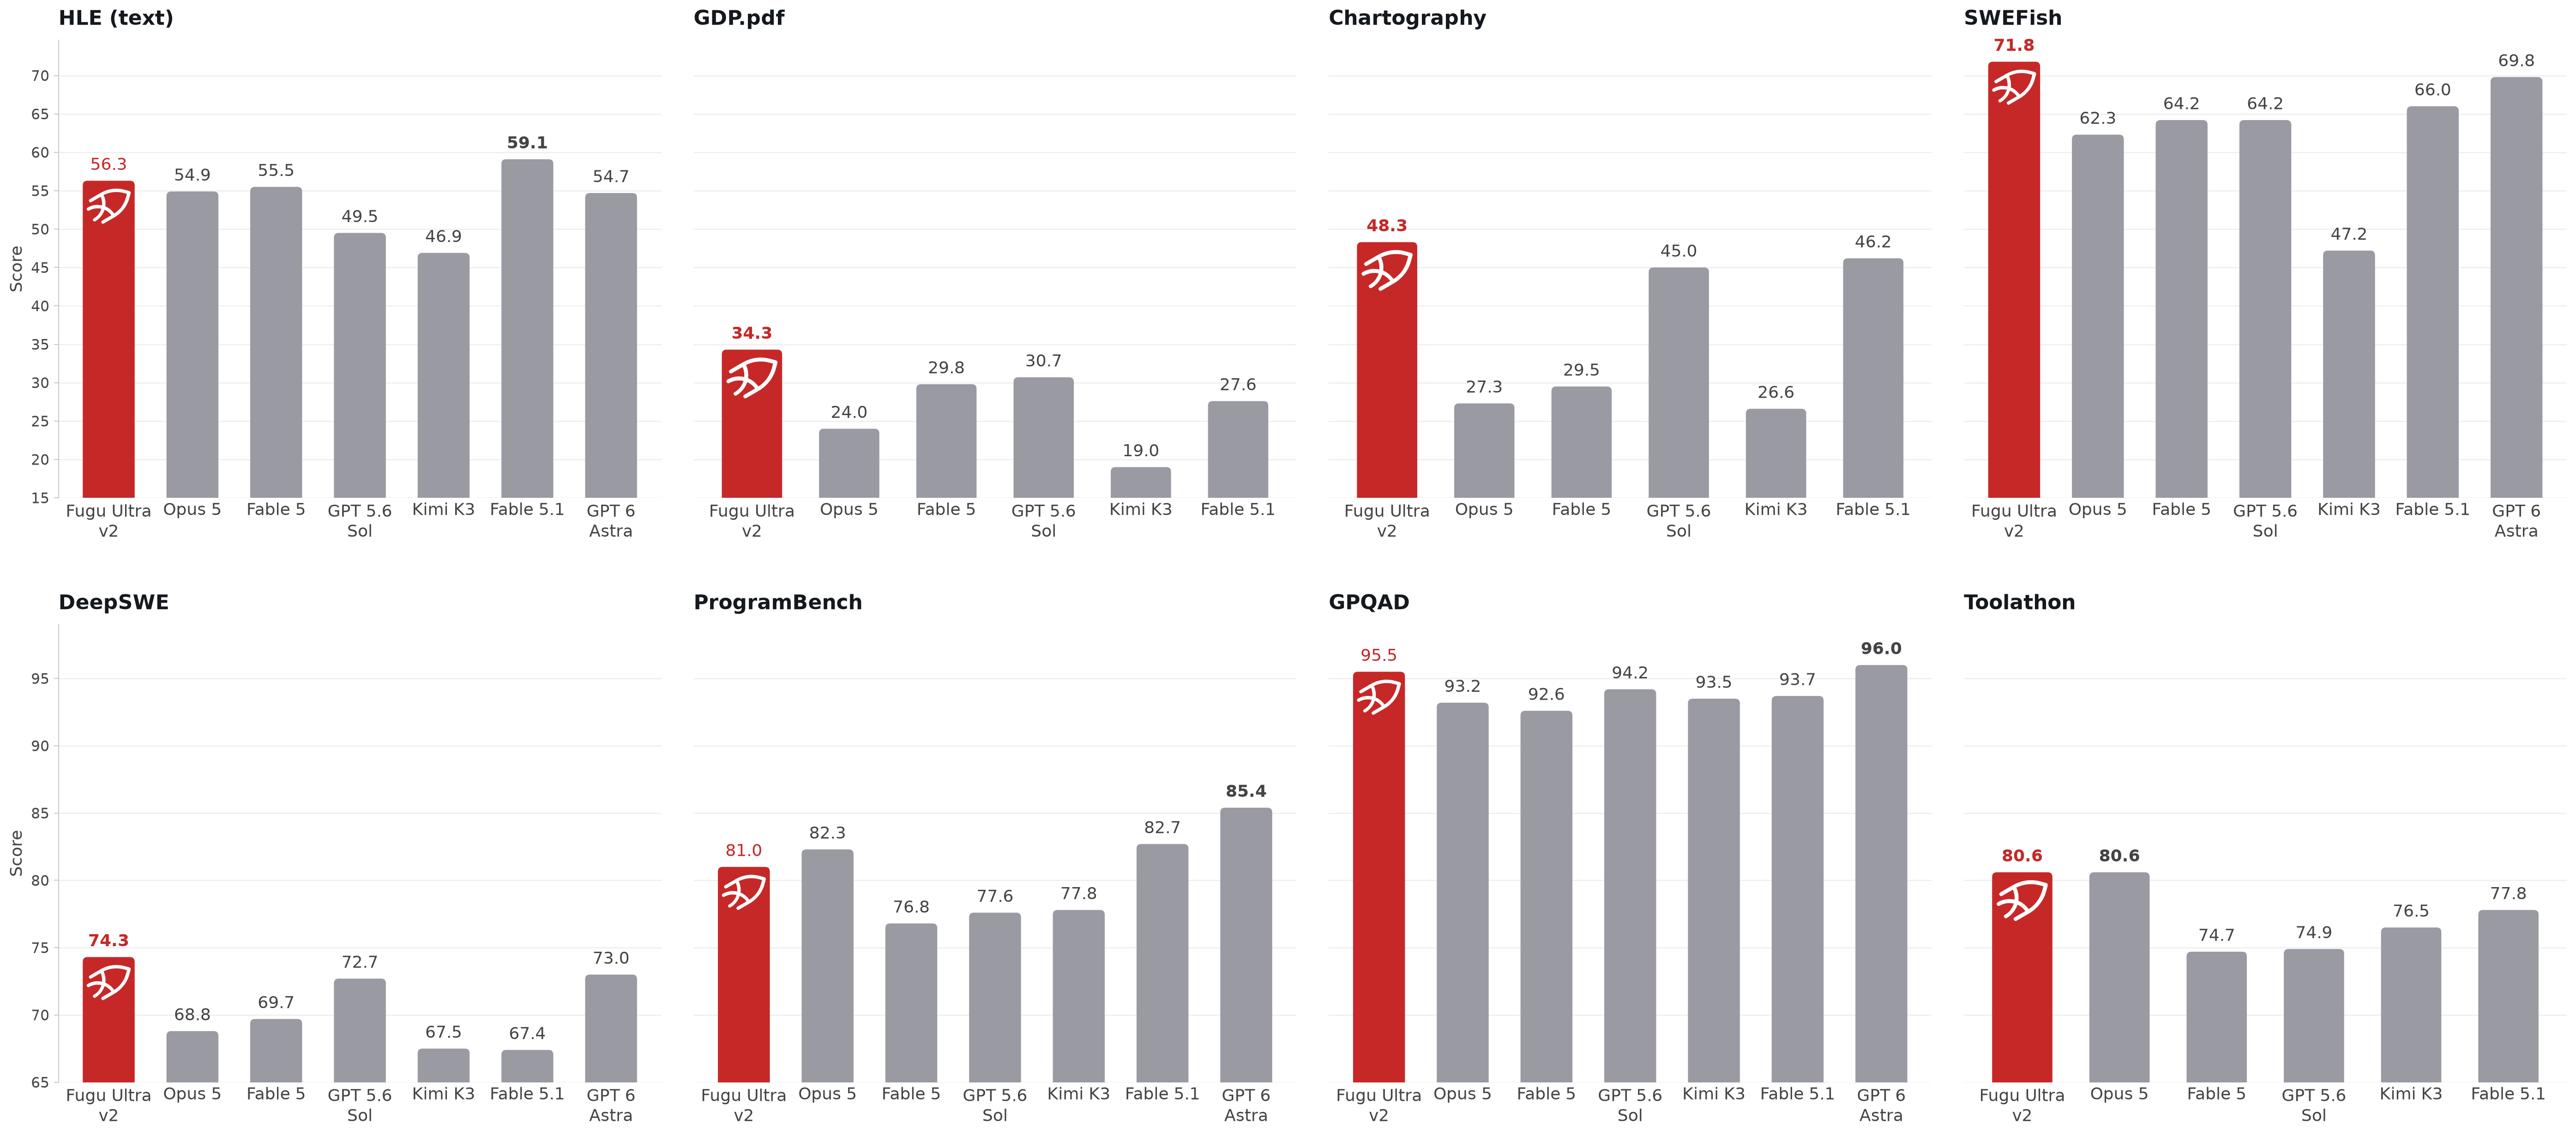
For complex multi-step reasoning, autonomous research, and full-stack software development, Fugu Ultra sets our new benchmark for raw output quality. In summary, Fugu Ultra
複雑なマルチステップ推論、自律型リサーチ、フルスタックソフトウェア開発において、Fugu Ultra は出力品質そのものに関する新たな基準を打ち立てます。Fugu Ultraの成果は以下の通りです。
-
Performance: Achieves the best or joint-best score on five of eight benchmarks: GDP.pdf, Chartography, DeepSWE, Toolathon, and SWEFish, our internal benchmark reflecting Sakana AI’s own coding challenges and use-cases.
性能:8 つのベンチマークのうち、GDP.pdf、Chartography、DeepSWE、Toolathon、そして Sakana AI 独自のコーディング課題やユースケースを反映した社内ベンチマークである SWEFish の 5 つで、単独最高または同率最高のスコアを達成しています。
-
Consistency: Places in the top 2 on seven of eight benchmarks, demonstrating strong performance across a broad range of agentic tasks.
一貫性:8 つのベンチマークのうち 7 つでトップ 2 に入り、幅広いエージェント型タスクで高い性能を発揮しています。
-
Frontier: With a focus different from Fugu Max, Fugu Ultra pushes the Pareto frontier in the performance direction, providing a higher-capability option for workloads where quality is the priority.
フロンティア:Fugu Max とは異なる方向性で、Fugu Ultra はパレートフロンティアを性能方向へ押し広げ、品質を最優先するワークロードにより高い能力を提供します。
Fugu Ultra does not rely on individual proprietary frontier models to deliver frontier output. By orchestrating a swappable pool of open and specialized models, it outperforms closed ecosystems while protecting users from vendor lock-in, API revocations, geopolitical turbulence, and sudden service cutoffs.
Fugu Ultra は、フロンティアレベルの出力を実現するために、個別のプロプライエタリなフロンティアモデルへ依存していません。入れ替え可能なオープンモデルと専門モデルのプールをオーケストレーションすることで、クローズドなエコシステムを上回る性能を発揮しながら、ベンダーロックイン、API の提供停止、地政学的な不確実性、突然のサービス遮断からユーザーを保護します。
Our flagship Fugu Ultra model continues to deliver a performance that is better or on-par with frontier models. Note: Fugu Ultra’s training cutoff date is 20260828, Fable 5, Fable 5.1 and GPT-6-Astra are NOT in Fugu-Ultra’s model pool.
フラッグシップモデルである Fugu Ultra は、引き続きフロンティアモデルを上回る、または同等の性能を発揮しています。注:Fugu Ultra の学習データのカットオフ日は 20260828 であり、Fable 5、Fable 5.1、GPT-6-Astra は Fugu Ultra のモデルプールに含まれていません。
Fugu Max (v1.0)
Fugu Max expands the pool of models Sakana Fugu can orchestrate, integrating an unprecedented number of open-weights and specialized models, including NVIDIA's Nemotron family through our collaboration with NVIDIA. It sits at a point on the Pareto frontier that single-model providers cannot reach. Concretely,
Fugu Max は、Sakana Fugu がオーケストレーションできるモデルプールを拡大し、NVIDIA との協業を通じて利用する NVIDIA の Nemotron ファミリーを含む、これまでにない数のオープンウェイトモデルと専門モデルを統合しています。単一モデルのプロバイダーでは到達できないパレートフロンティア上の位置を実現しています。具体的には、
-
Performance: Fugu Max achieves best overall score on six benchmarks, including Terminal Bench 2.1, GPQAD, AA-LCR, GDP.pdf, AutomationBench, and SWEFish, our internal benchmark reflecting Sakana AI’s own coding challenges and use-cases.
性能:Fugu Max は、Terminal Bench 2.1、GPQAD、AA-LCR、GDP.pdf、AutomationBench、そして Sakana AI 独自のコーディング課題やユースケースを反映した社内ベンチマークである SWEFish を含む 6 つのベンチマークで、総合最高スコアを達成しています。
-
Cost: At $2 per million input tokens and $6 per million output tokens, Fugu Max’s output pricing is 40-60% lower than Sonnet 5, GPT 5.6 Terra, and Kimi K3.
コスト:Fugu Max は入力 100 万トークンあたり $2、出力 100 万トークンあたり $6 で、出力料金は Sonnet 5、GPT 5.6 Terra、Kimi K3 より 40〜60% 低く設定されています。
-
Efficiency: Fugu Max expands the cost-performance Pareto frontier on seven out of ten benchmarks, delivering performance beyond the existing baseline efficiency envelope.
効率性:Fugu Max は 10 のベンチマークのうち 7 つでコストパフォーマンスのパレートフロンティアを押し広げ、既存のベースラインが形成する効率性の領域を超える性能を実現しています。
Among frontier models in a similar price range (input prices per 1M tokens for each model are shown in the first subplot), Fugu Max expands the pareto frontier formed by single models and places itself in a cost-performance efficient position across multiple benchmarks.
同価格帯のフロンティアモデル(各モデルの入力 100 万トークンあたりの料金は最初のサブプロットに表示)の中で、Fugu Max は単一モデル群が形成するパレートフロンティアを押し広げ、複数のベンチマークにわたってコスト-パフォーマンスの優位性を実現しています。
Fugu Cyber (v1.0)
For cybersecurity workflows that demand deep technical reasoning and careful investigation, Fugu Cyber applies multi-agent orchestration to security analysis, vulnerability research, and threat investigation. By coordinating specialized agents, it can sustain complex investigative workflows where precision and depth matter.
高度な技術的推論と慎重な調査が求められるサイバーセキュリティ領域において、Fugu Cyber はマルチエージェント・オーケストレーションをセキュリティ分析、脆弱性調査、脅威調査に活用します。専門エージェントを連携させることで、精度と深さが重要となる複雑な調査ワークフローを継続的に遂行します。
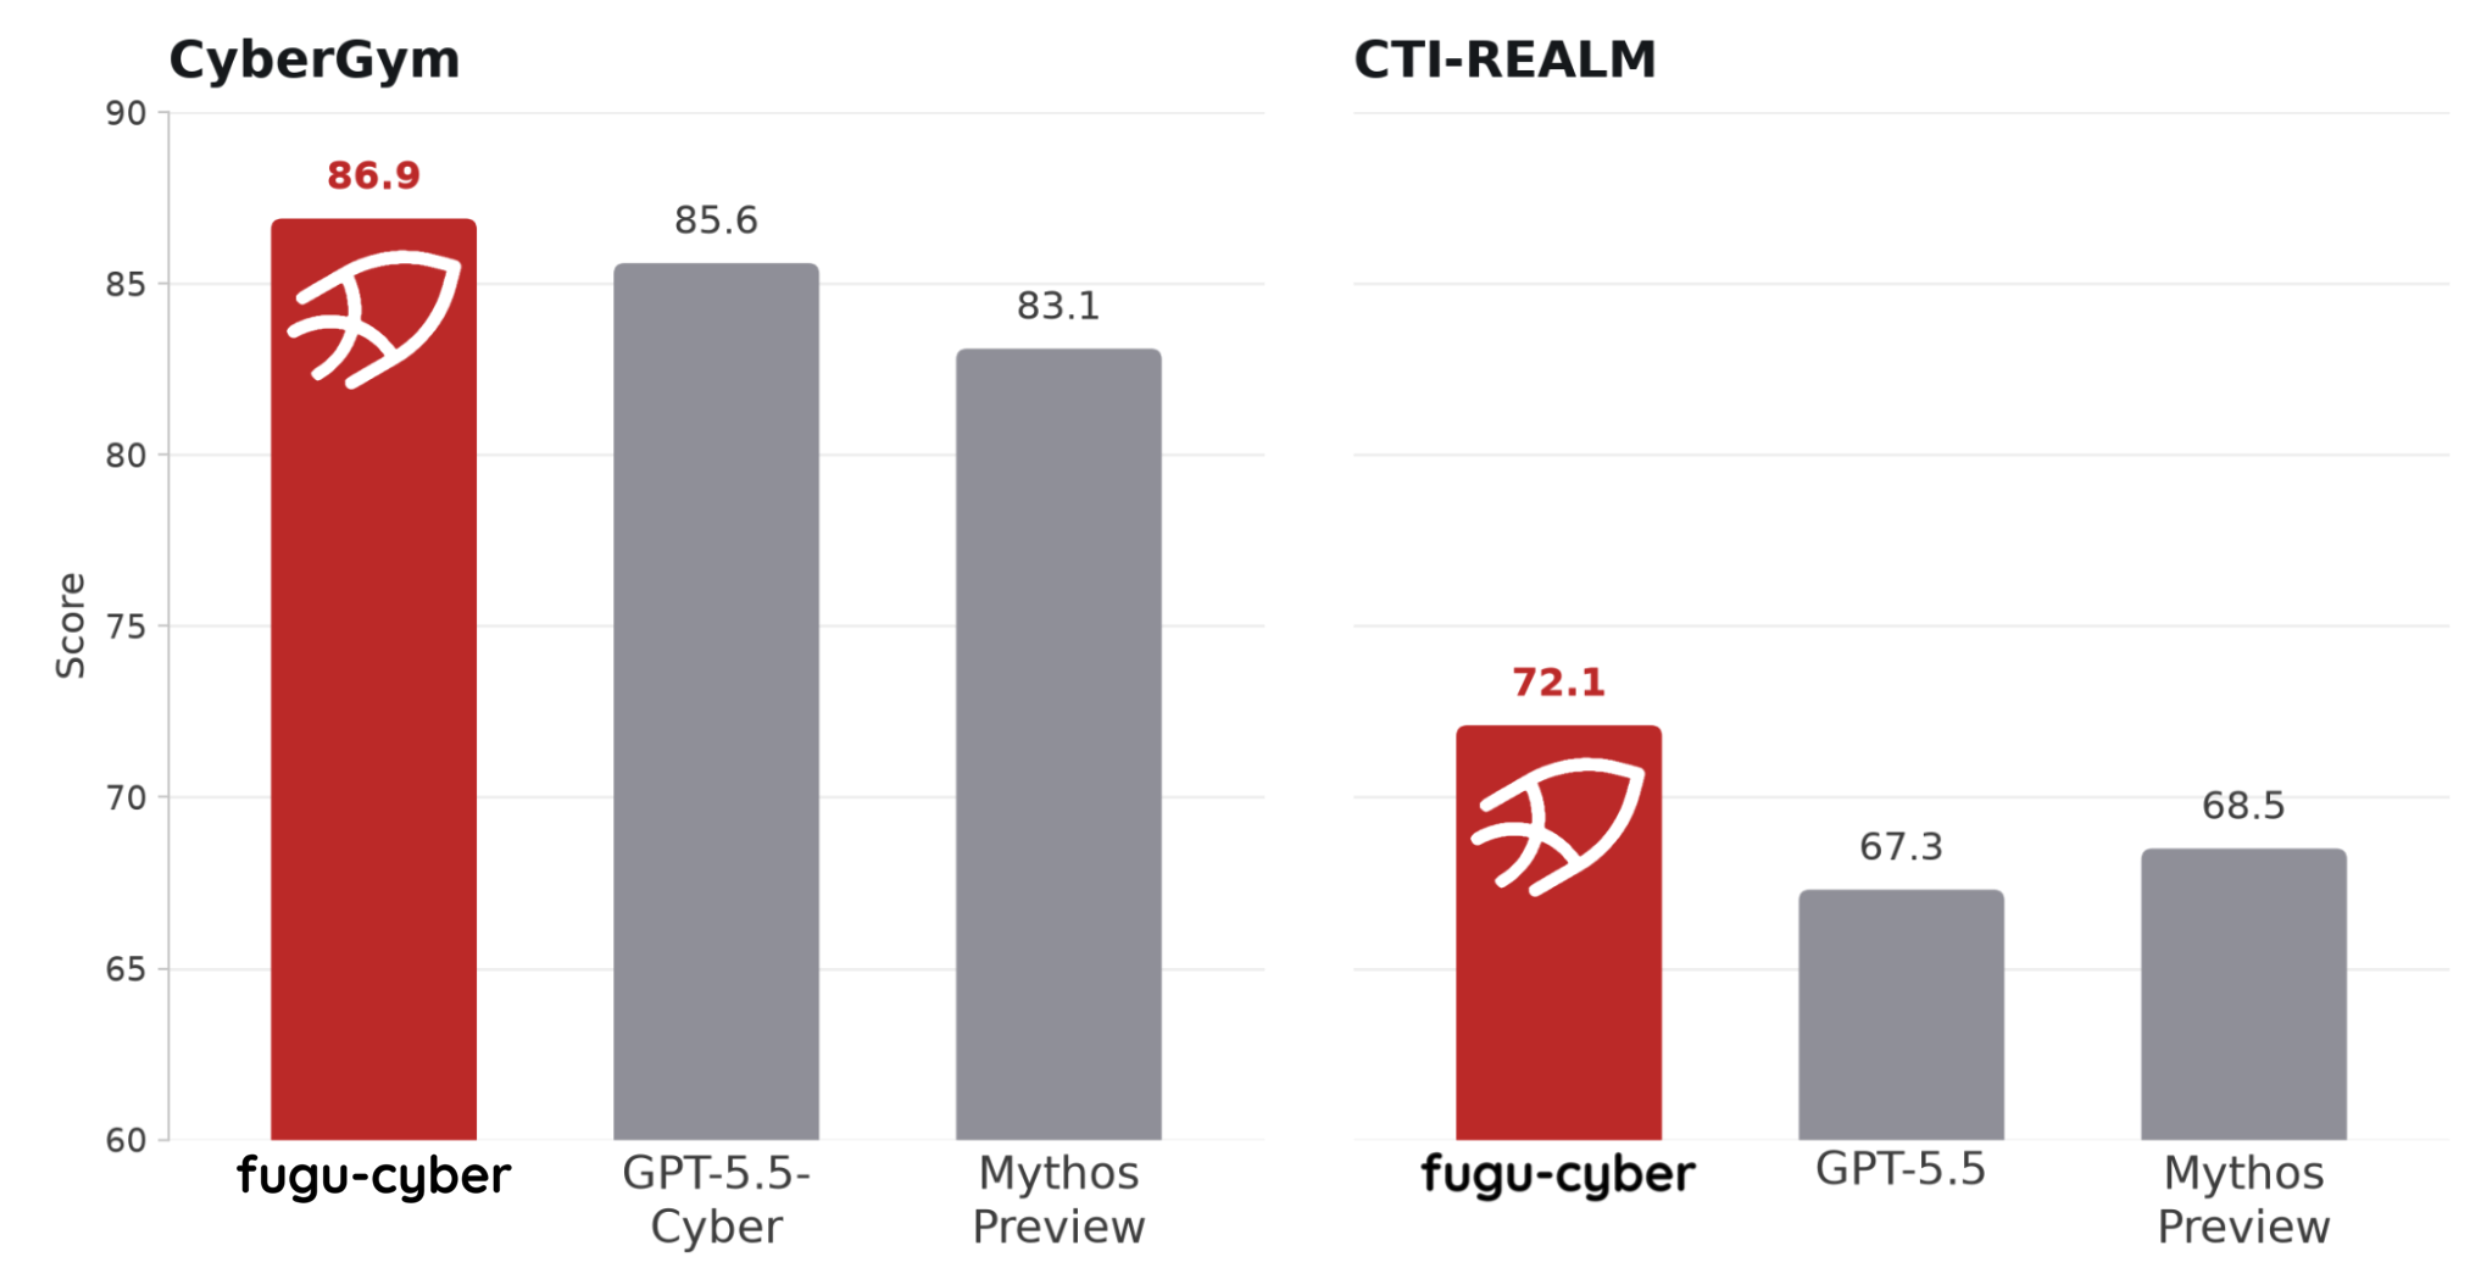
Fugu-Cyber achieves state-of-the-art performance on the industry's most challenging security benchmarks, reaching a success rate of 86.9% on CyberGym and 72.1% on CTI-REALM, comparable to leading cybersecurity-focused frontier models such as GPT-5.5-Cyber and Mythos-Preview.
Fugu-Cyber は、業界で最も難しいセキュリティベンチマークにおいて最先端の性能を達成し、CyberGym で 86.9%、CTI-REALM で 72.1% の成功率に到達しました。これは GPT-5.5-Cyber や Mythos-Preview など、サイバーセキュリティに特化した主要なフロンティアモデルに匹敵する結果です。